Introduction
How fast can one machine really go.
VeloXel is a native C++20 image/frame-processing engine built around a rigorous optimization story: start from a clean scalar baseline, then earn every speedup — tiled multithreading, then hand-written SIMD — with benchmarks proving each step.
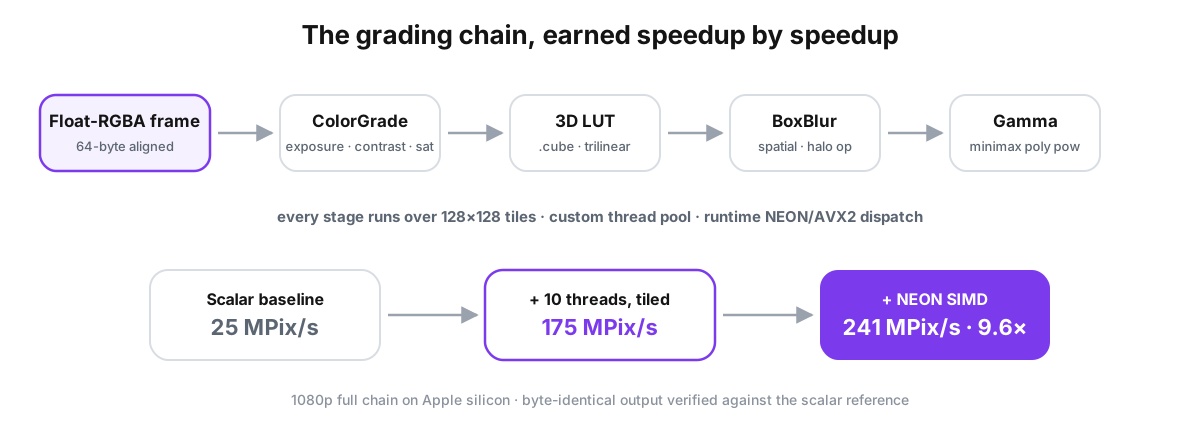
The engine applies a fixed color-grading chain (ColorGrade → 3D LUT → BoxBlur → Gamma) to float-RGBA frames, and ships VeloXel Studio, a DaVinci-Resolve-styled grading GUI on top.
Architecture
Tiles, ops and a hand-rolled thread pool.
Frames live in 64-byte-aligned flat float buffers. Every processing stage implements a tile interface with an explicit aliasing contract separating in-place point ops from spatial ops that need scratch memory. A pipeline runs the chain either as a scalar reference or fanned out over 128×128 tiles through a custom condition-variable thread pool — with byte-identical output guaranteed between the two.
Correctness is enforced by tooling: an image-diff utility holds every optimized path to within one 8-bit step of the scalar reference.
Going wide
NEON and AVX2, dispatched at runtime.
Per-architecture kernels are hand-vectorized: NEON on arm64 using structured de-interleaving loads, AVX2 + FMA on x86 with in-register interleaving and gathers — selected by runtime CPU detection, never coexisting in one binary.
The flagship trick: a vectorized polynomial pow for gamma correction (exp2(k·log2 x) with a degree-5 minimax polynomial) that beats the libm call the auto-vectorizer can't touch — 4× on that kernel alone. The 3D LUT stage does gather-based trilinear interpolation with Resolve/Adobe .cube parsing.
The studio
A grading UI that never blocks.
VeloXel Studio is an ImGui + GLFW/OpenGL app styled after DaVinci Resolve: Lift/Gamma/Gain color wheels, a node graph with live per-stage thumbnails, RGB parade and histogram scopes, drag-and-drop images and .cube LUTs, and live switches for SIMD level and tile size.
Rendering runs on a worker thread with a latest-wins mailbox, so dragging a color wheel re-renders continuously without ever freezing the UI thread.
9.6×
full-chain speedup at 1080p — 25 → 241 MPix/s
250 MPix/s
full grading chain at 4K on Apple silicon
4.0×
gamma kernel gain from the NEON minimax pow
What's inside
Key features.
Custom thread pool
Condition-variable pool fanning the frame out over 128×128 tiles with a barrier between stages.
Hand-written SIMD
NEON and AVX2+FMA kernel translation units behind runtime CPUID dispatch.
Vectorized pow
Degree-5 minimax polynomial gamma — 4× over libm on the same hardware.
3D LUT engine
Gather-based trilinear interpolation with industry-standard .cube file parsing.
Benchmark suite
Google Benchmark per-kernel and full-chain runs reporting MPix/s at 720p, 1080p and 4K.
Bit-exact verification
img_diff tooling enforces ≤1 8-bit step deviation between scalar and optimized paths.
VeloXel Studio
Resolve-style GUI: color wheels, node graph, scopes, drag-drop LUTs, live SIMD toggles.
Cross-ISA builds
arm64-native with x86_64 AVX2 correctness validated under Rosetta 2.
Built with